Grepsr Alternatives in 2026: 9 Web Data Tools Compared
Grepsr sells managed web scraping on custom quotes. Here are nine Grepsr alternatives — self-serve scrapers, scraping APIs, and B2B contact data providers — with honest notes on pricing, speed, and where each one breaks.
TL;DR
- Grepsr is a managed data-as-a-service company: you describe the dataset, their team builds and maintains the crawler, you get files or API delivery. That model is great for messy, high-volume crawls and slow for anything you need this afternoon.
- Most teams shopping for Grepsr alternatives want one of three things: self-serve control (Apify, Octoparse), infrastructure-only scraping (Bright Data, Zyte, ScrapingBee), or ready-made B2B contact data (Tomba, BookYourData, Diffbot).
- If your "web data" project is really "I need verified work emails and phone numbers for a target account list," a scraping vendor is the expensive way to get there. A contact API solves it in an afternoon.
- Budget reality: self-serve scraping platforms start near $49–$99/mo. Managed crawling contracts typically land in the four figures per month once volume and maintenance are priced in.
- No single tool wins. Pick by who maintains the crawler when the site changes — that's the cost line everyone underestimates.
What is Grepsr and who actually uses it?#
Grepsr is a managed web data extraction service. You submit a requirement — "every product listing on these 40 retail domains, refreshed weekly, normalized to this schema" — and Grepsr's team builds the crawler, runs it, handles blocks and layout changes, and delivers the output to S3, FTP, a database, or an API endpoint.
The buyers are usually data teams, market-intelligence groups, and e-commerce pricing teams at companies where nobody wants to own a scraping stack. You're not buying software. You're buying an outcome plus a human team that keeps the outcome working.
That's the whole value proposition, and it's a real one. It's also why people go looking for alternatives:
- Pricing is quote-based, so you can't self-serve or test cheaply.
- Turnaround on a new dataset is measured in days or weeks, not minutes.
- You don't own the extraction logic — offboarding means rebuilding.
- For common data types (company firmographics, contact details, job posts), you're paying custom-crawl prices for something several vendors already sell as a standard product.
Wait — that renders wrong. Here it is properly:
Why do teams look for Grepsr alternatives?#
In practice, four triggers come up over and over.
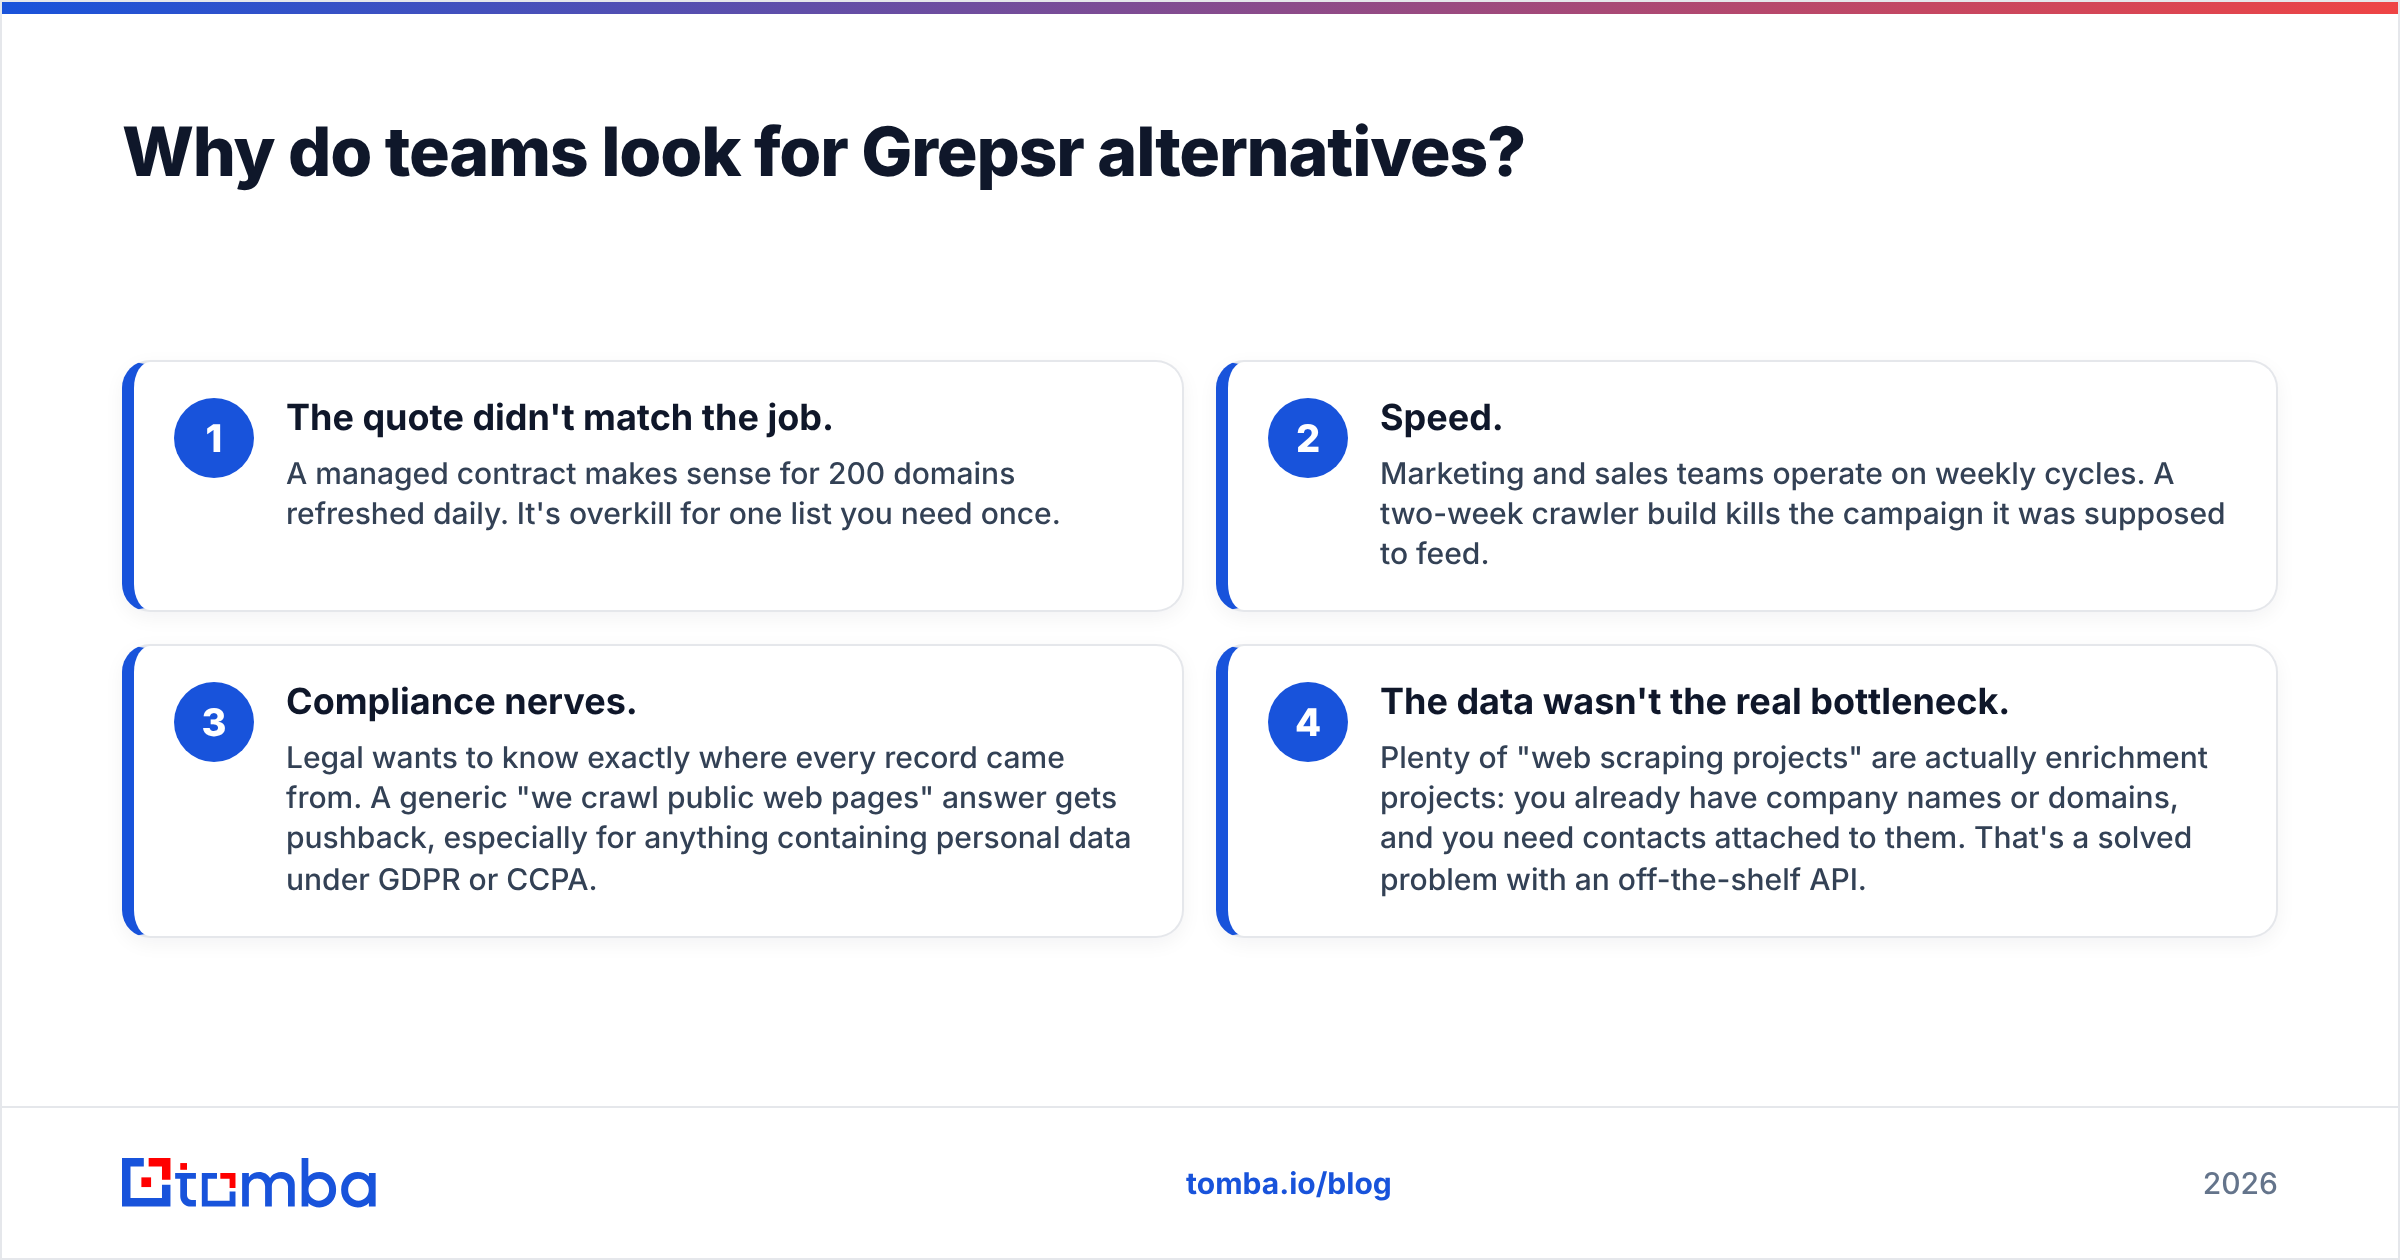
- The quote didn't match the job. A managed contract makes sense for 200 domains refreshed daily. It's overkill for one list you need once.
- Speed. Marketing and sales teams operate on weekly cycles. A two-week crawler build kills the campaign it was supposed to feed.
- Compliance nerves. Legal wants to know exactly where every record came from. A generic "we crawl public web pages" answer gets pushback, especially for anything containing personal data under GDPR or CCPA.
- The data wasn't the real bottleneck. Plenty of "web scraping projects" are actually enrichment projects: you already have company names or domains, and you need contacts attached to them. That's a solved problem with an off-the-shelf API.
If you recognize #4, skip ahead to the contact-data section. You'll save a quarter.
What should you compare before switching?#
Use these six criteria, in this order. They predict switching regret better than feature lists do.
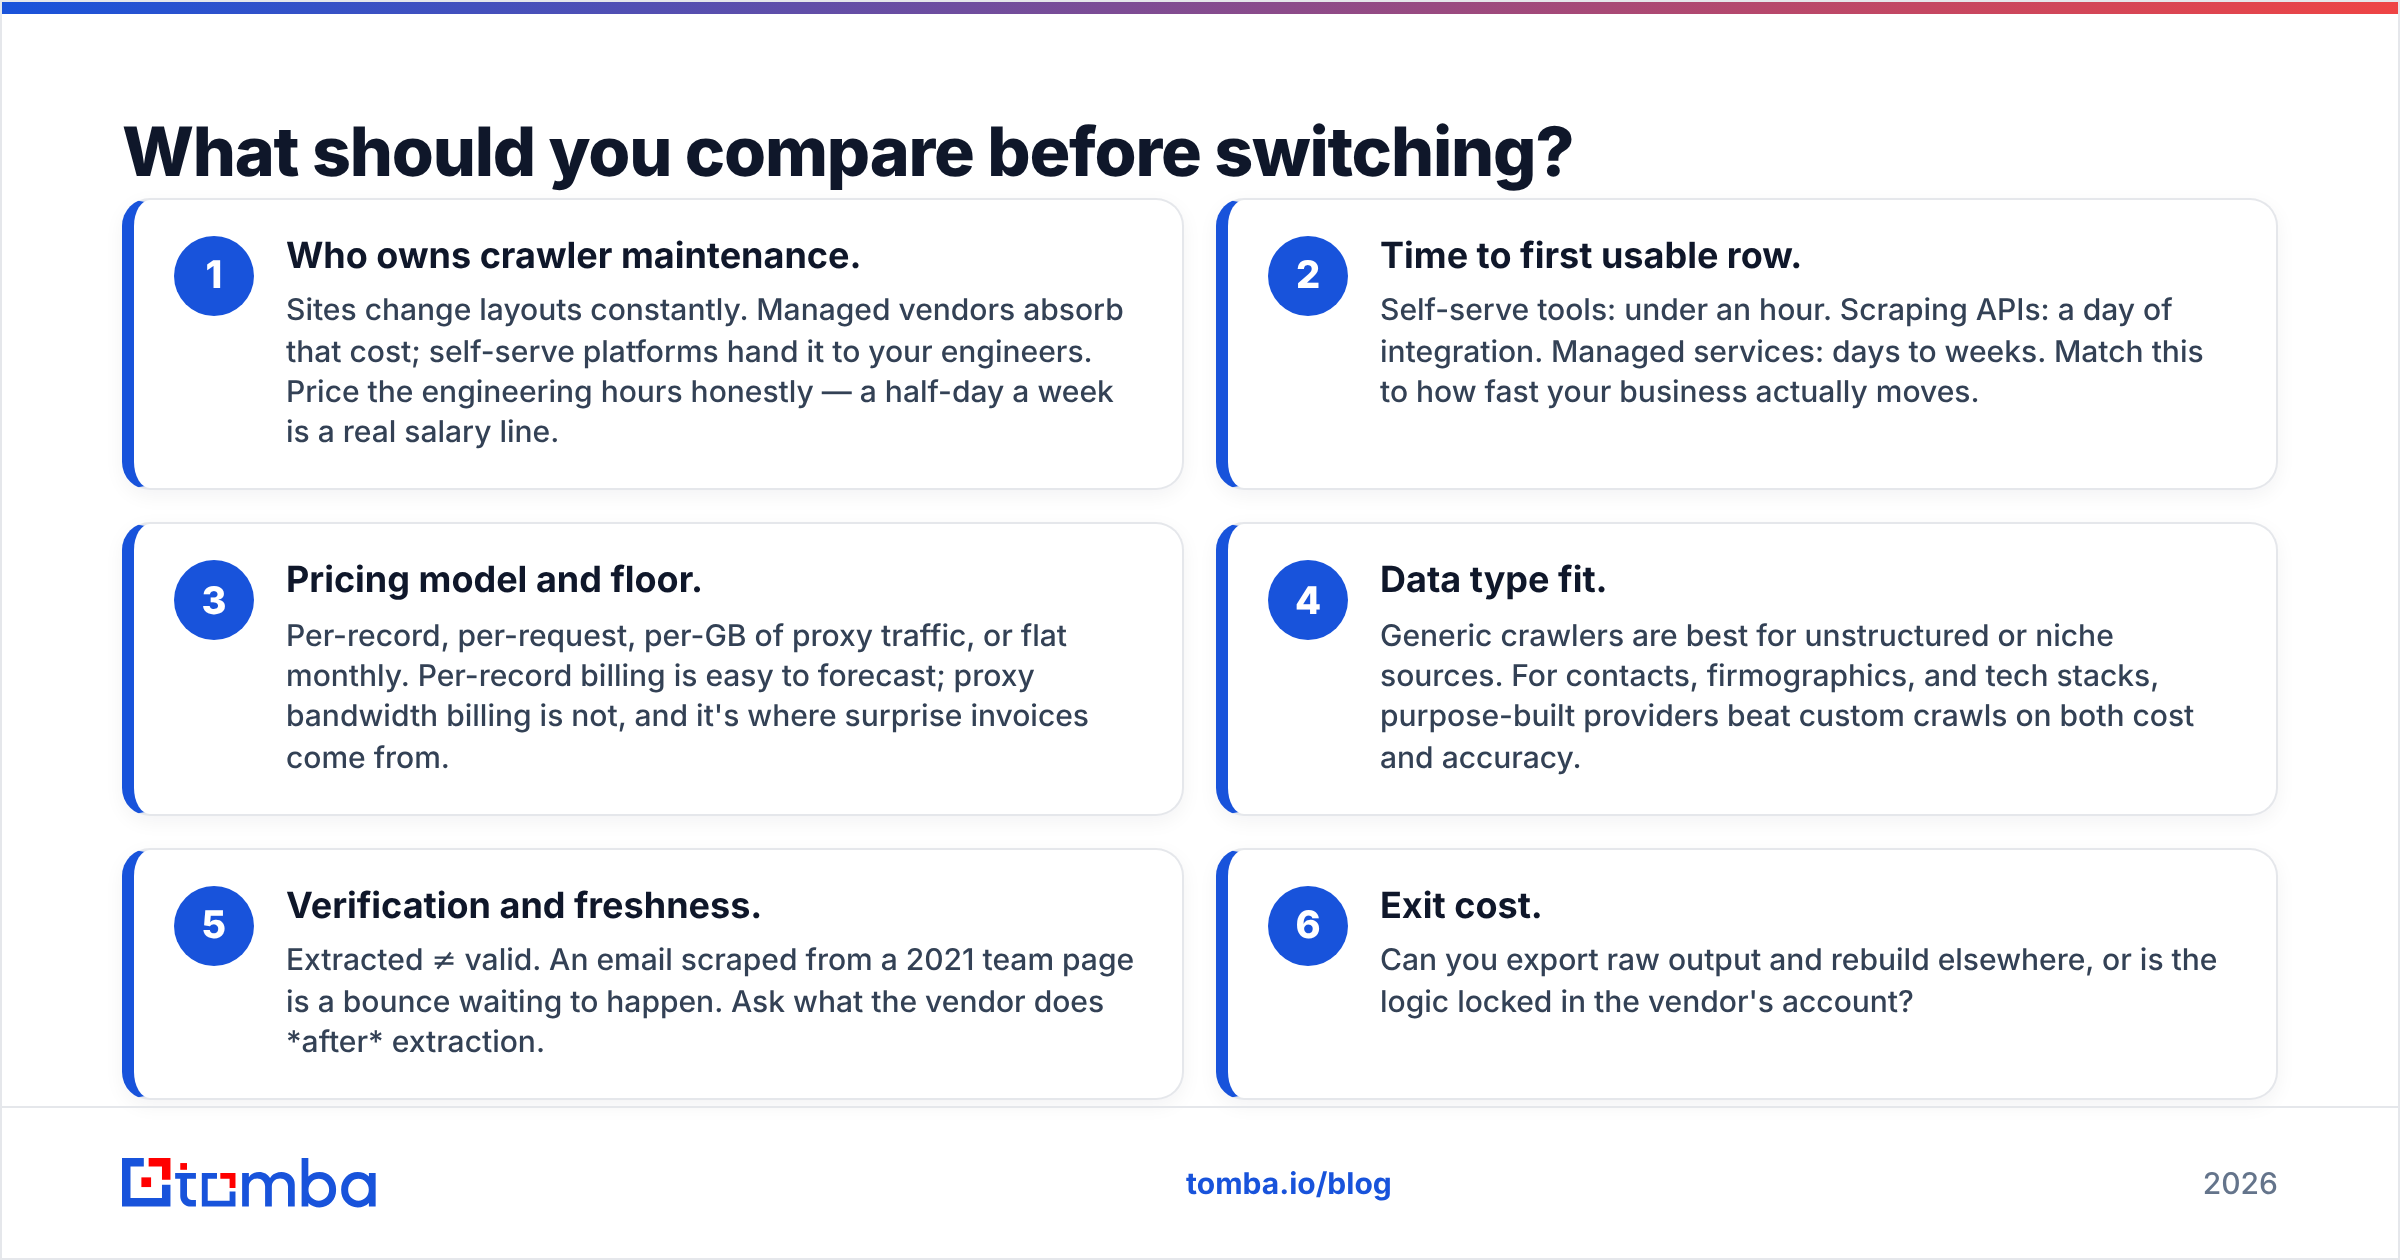
- Who owns crawler maintenance. Sites change layouts constantly. Managed vendors absorb that cost; self-serve platforms hand it to your engineers. Price the engineering hours honestly — a half-day a week is a real salary line.
- Time to first usable row. Self-serve tools: under an hour. Scraping APIs: a day of integration. Managed services: days to weeks. Match this to how fast your business actually moves.
- Pricing model and floor. Per-record, per-request, per-GB of proxy traffic, or flat monthly. Per-record billing is easy to forecast; proxy bandwidth billing is not, and it's where surprise invoices come from.
- Data type fit. Generic crawlers are best for unstructured or niche sources. For contacts, firmographics, and tech stacks, purpose-built providers beat custom crawls on both cost and accuracy.
- Verification and freshness. Extracted ≠ valid. An email scraped from a 2021 team page is a bounce waiting to happen. Ask what the vendor does after extraction.
- Exit cost. Can you export raw output and rebuild elsewhere, or is the logic locked in the vendor's account?
What are the best Grepsr alternatives in 2026?#
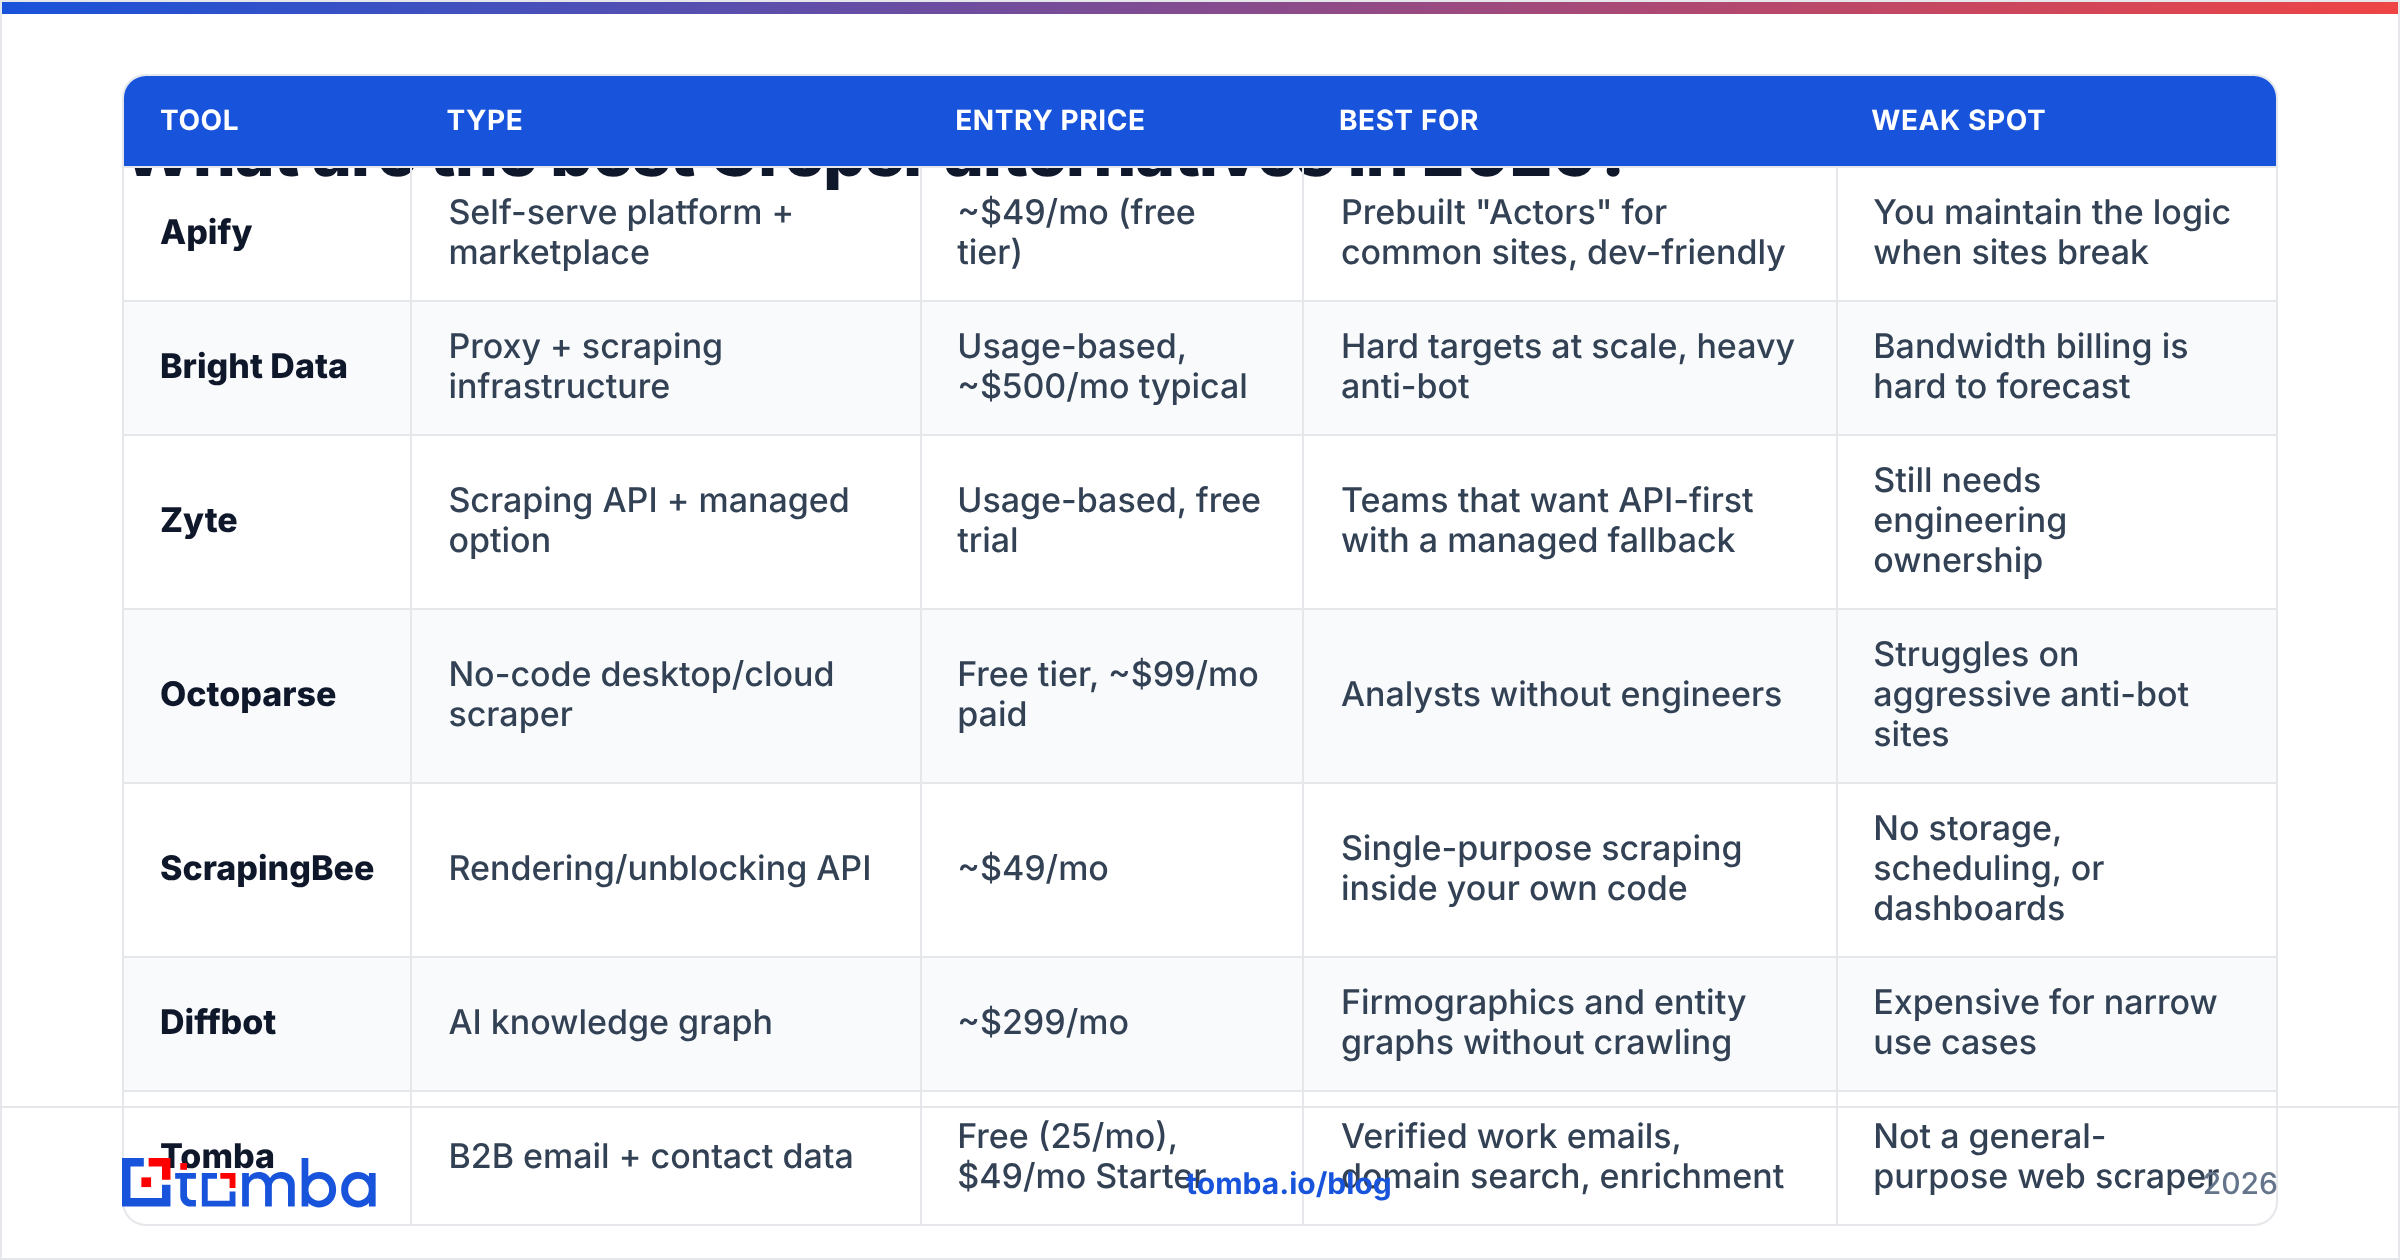
Here's the comparison table. Treat prices as directional — every vendor on this list has repriced in the last 18 months, so confirm on their site before you sign anything.
| Tool | Type | Entry price | Best for | Weak spot |
|---|---|---|---|---|
| Apify | Self-serve platform + marketplace | ~$49/mo (free tier) | Prebuilt "Actors" for common sites, dev-friendly | You maintain the logic when sites break |
| Bright Data | Proxy + scraping infrastructure | Usage-based, ~$500/mo typical | Hard targets at scale, heavy anti-bot | Bandwidth billing is hard to forecast |
| Zyte | Scraping API + managed option | Usage-based, free trial | Teams that want API-first with a managed fallback | Still needs engineering ownership |
| Octoparse | No-code desktop/cloud scraper | Free tier, ~$99/mo paid | Analysts without engineers | Struggles on aggressive anti-bot sites |
| ScrapingBee | Rendering/unblocking API | ~$49/mo | Single-purpose scraping inside your own code | No storage, scheduling, or dashboards |
| Diffbot | AI knowledge graph | ~$299/mo | Firmographics and entity graphs without crawling | Expensive for narrow use cases |
| Tomba | B2B email + contact data | Free (25/mo), $49/mo Starter | Verified work emails, domain search, enrichment | Not a general-purpose web scraper |
| BookYourData | Prebuilt B2B contact lists | Pay-as-you-go credits | Instant list purchase, no build phase | List-based rather than live crawling |
| PhantomBuster | Social/web automation | ~$69/mo | LinkedIn and social workflows | Platform-specific, rate-limited |
Apify — the closest self-serve equivalent#
Apify is what most Grepsr refugees try first. It's a cloud platform where scrapers ("Actors") run as containers, plus a marketplace of thousands of prebuilt ones for common targets. You get scheduling, storage, proxies, and webhooks without building infrastructure.
The trade: Grepsr's team fixes your crawler at 2 a.m. when a target site redesigns. On Apify, that's your ticket. If you have even one developer who enjoys this work, Apify is cheaper and dramatically faster to start.
Bright Data and Oxylabs — infrastructure, not outcomes#
These are the heavyweight proxy and unblocking networks. If your problem is "the target site aggressively blocks us," this is the layer that solves it. Both now sell higher-level scraper APIs and prebuilt datasets on top of the proxy business.
Be careful with pricing. Bandwidth-metered plans are excellent value at predictable volumes and brutal when a crawler misbehaves. Set hard caps on day one.
Zyte — API-first with an escape hatch#
Zyte's API handles bans, rendering, and retries, and they'll also run projects managed if you need the Grepsr model without leaving the platform. That dual mode is genuinely useful: prototype yourself, hand it off if it becomes load-bearing.
Octoparse — for analysts without engineers#
Point-and-click extraction, cloud scheduling, templates for popular sites. It's the right call when the person who needs the data is the person building the scraper and that person writes SQL, not Python. It falls over on sites with serious bot defenses.
Diffbot — buy the graph, skip the crawl#
Diffbot crawls the web itself and sells structured entities: companies, people, articles, products. For firmographic enrichment, this replaces a custom crawl entirely. The entry price is high enough that it only pays off if you're querying at volume.
Tomba — when "web data" actually means "contacts"#
Here's the uncomfortable question worth asking before you sign any scraping contract: what percentage of your requested dataset is just names, work emails, and phone numbers?
If the answer is most of it, a general crawler is the wrong tool. Tomba does this specific job natively — domain search returns every discoverable address at a company with its pattern and confidence score, the email verifier checks deliverability before you send, and the Tomba API drops the whole thing into your existing pipeline.
Concretely: a managed crawl of 5,000 company sites to harvest team-page emails is weeks of build time, no verification layer, and no coverage of people who aren't listed publicly. Running the same 5,000 domains through a bulk lookup is an afternoon and includes verification. Tomba pricing runs Free (25 searches/mo), Starter $49/mo, Growth $99/mo, Pro $249/mo, and Enterprise on request — which is roughly the difference between a rounding error and a procurement cycle.
Where Tomba is not the answer: product catalogs, pricing pages, review scraping, job boards, real-estate listings. Those are genuine crawler jobs. Use a crawler.
BookYourData — buy the list, skip the build#
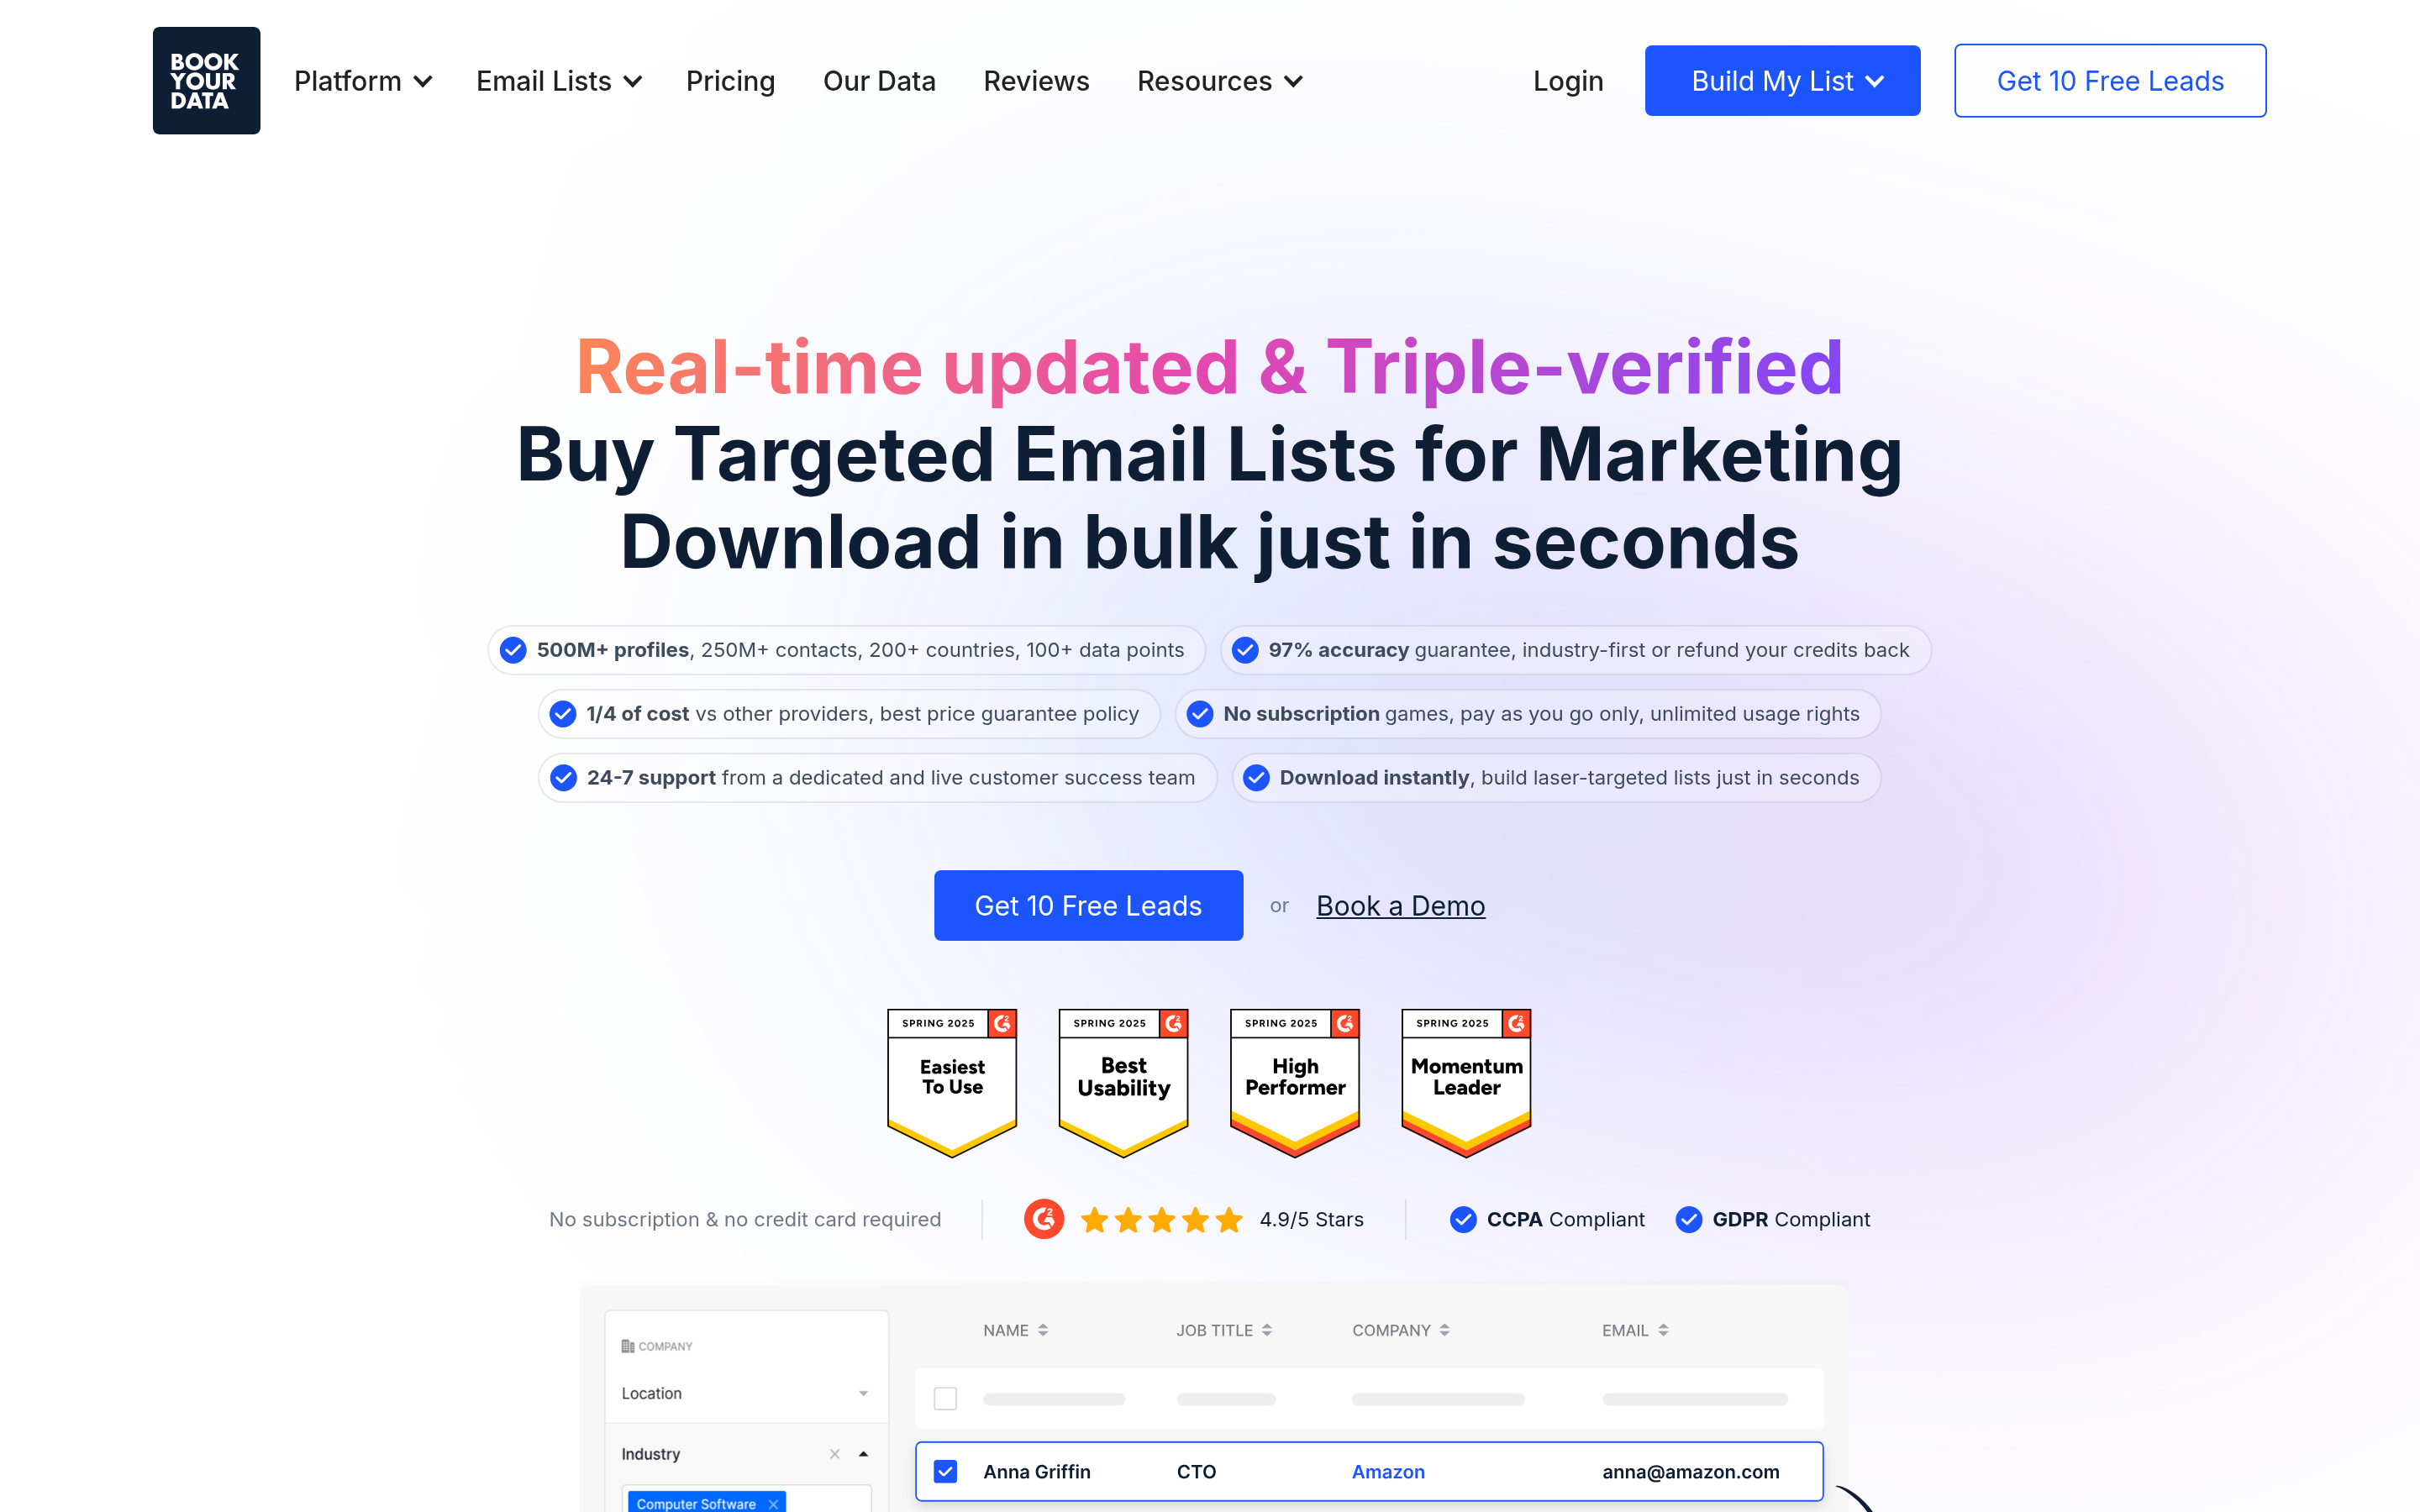
BookYourData sells prebuilt, filterable B2B contact lists on a pay-as-you-go credit model with an accuracy guarantee. It's a legitimately different shape of solution: instead of building a pipeline, you filter by industry, title, geography, and company size, then export.
That suits one-off campaigns and teams without engineering support very well. It's a strong option when you know exactly who you want and you want it today. Where a live API pulls ahead is continuous enrichment — new signups, inbound leads, CRM records going stale — because those need lookups on demand rather than a snapshot.
PhantomBuster and the social-automation tier#
If your target is LinkedIn, X, or Instagram rather than the open web, general scrapers underperform and platform-specific tools handle session management, rate limits, and pagination. Useful, narrow, and worth knowing that platform terms of service change frequently here.
Managed service or self-serve — which model fits you?#
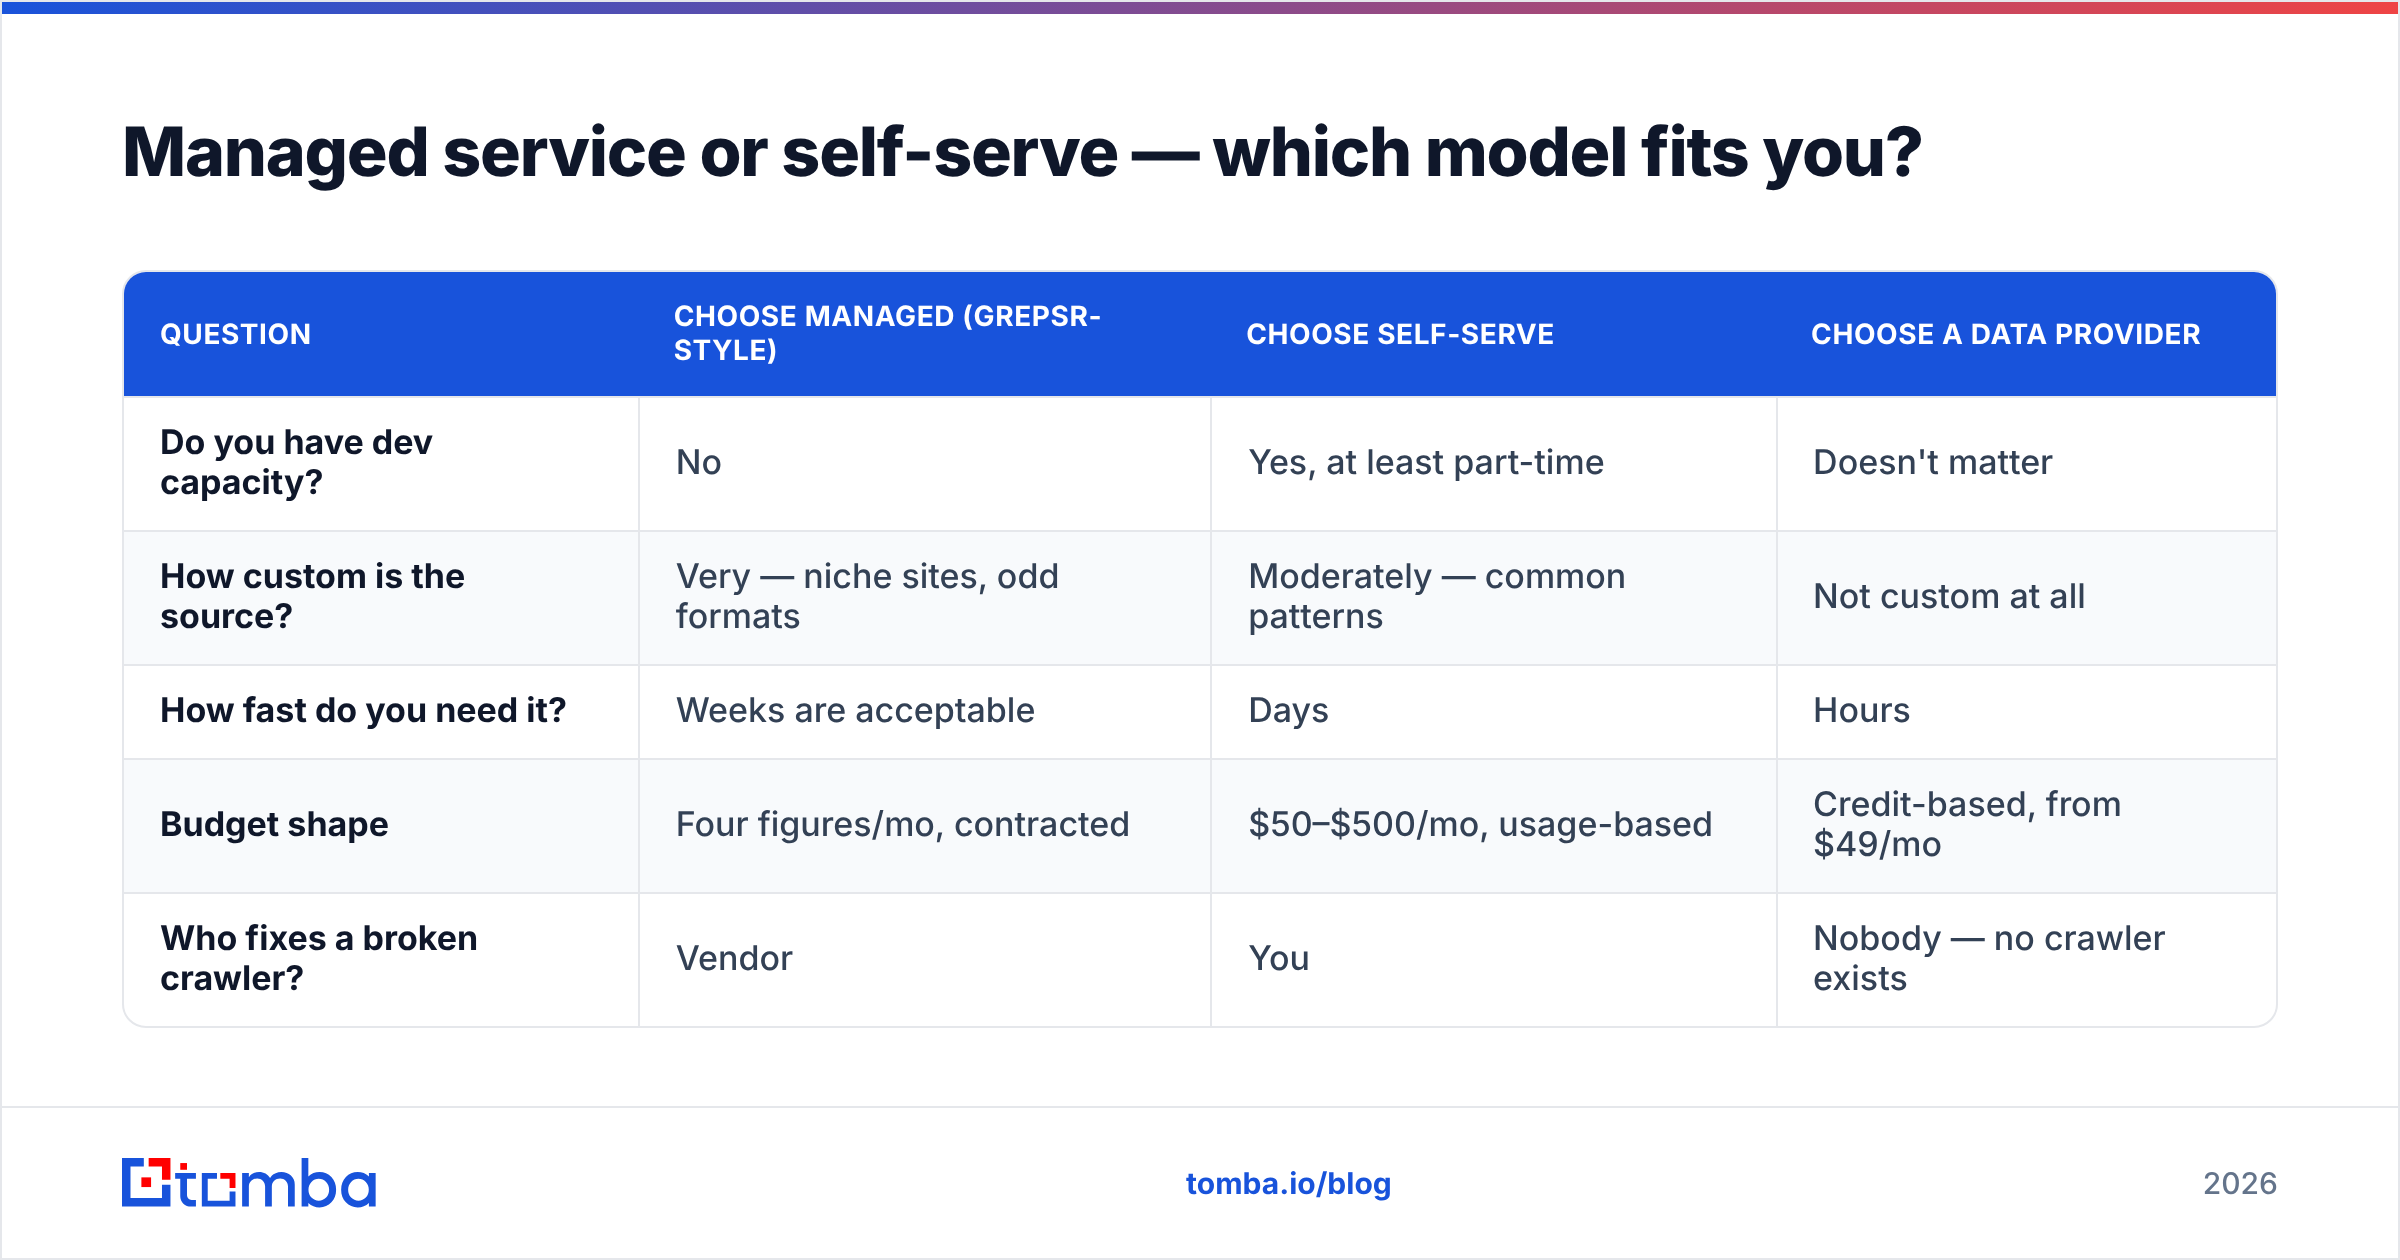
The tooling debate is downstream of one org question: does your team want to own extraction logic?
| Question | Choose managed (Grepsr-style) | Choose self-serve | Choose a data provider |
|---|---|---|---|
| Do you have dev capacity? | No | Yes, at least part-time | Doesn't matter |
| How custom is the source? | Very — niche sites, odd formats | Moderately — common patterns | Not custom at all |
| How fast do you need it? | Weeks are acceptable | Days | Hours |
| Budget shape | Four figures/mo, contracted | $50–$500/mo, usage-based | Credit-based, from $49/mo |
| Who fixes a broken crawler? | Vendor | You | Nobody — no crawler exists |
Read the last row twice. It's the one that determines total cost of ownership, and it's the one nobody models before signing.
Is scraped web data good enough for outbound?#
Usually not on its own — and this is where the switching decision gets decided for sales teams.
Scraping gets you a string that looks like an email address. It doesn't tell you whether the mailbox exists, whether the person still works there, or whether the domain is a catch-all that accepts everything and delivers nothing. Send to raw scraped output and your bounce rate climbs, which damages sender reputation, which quietly wrecks the deliverability of every campaign after it.
Standard practice before any send:
- Verify syntax and MX records — cheap, catches obvious junk.
- Run SMTP-level checks — confirms the mailbox actually accepts mail.
- Flag catch-all domains separately — they need different handling and lower send volume.
- Re-verify anything older than 90 days — B2B contact data decays roughly 2–3% per month as people change jobs.
- Deduplicate across sources — merged lists always contain overlap.
A scraping vendor delivers step zero. A contact data platform delivers all five. If deliverability matters to your revenue number, that gap is the entire argument.
Which Grepsr alternative should you pick?#
Short version:
- Complex, ongoing, multi-source crawls with no engineering team — stay with a managed provider. Grepsr, Zyte's managed tier, or Bright Data's dataset service.
- Common targets, some dev capacity — Apify. Fastest path from idea to running scraper.
- Blocked by anti-bot defenses — Bright Data, Oxylabs, or ScrapingBee as an infrastructure layer under your own code.
- No engineers, moderate targets — Octoparse.
- Firmographics and company entities — Diffbot.
- Contacts, emails, and phone numbers — a contact data provider, not a scraper. Tomba for live API lookups and verification; BookYourData when you'd rather buy a filtered list outright.
Cross-check any shortlist against recent reviews on G2 before committing — pricing models in this category shift faster than the marketing pages admit.
Ready to skip the crawler build?#
If your Grepsr project brief mostly reads "find the people at these companies and get me their contact details," you don't need a custom crawl and you don't need a two-week scoping call. Run your domain list through the Tomba Email Finder, get verified work emails with confidence scores and source attribution, and push them straight into your CRM or sequencer through the API. The free tier covers 25 searches a month — enough to test your actual target list before spending anything, and enough to find out whether the expensive option was ever necessary.
Related guides#
Ready to find emails that actually work?
Join 150,000+ professionals who stopped guessing and started sending. Free credits on signup — no credit card required.
Get the Tomba newsletter
Practical outbound tactics and product updates — once every two weeks.
About the author